Question

Duplicate Check Rule - Customer vs Prospect

  • August 31, 2026
  • 1 reply
  • 11 views

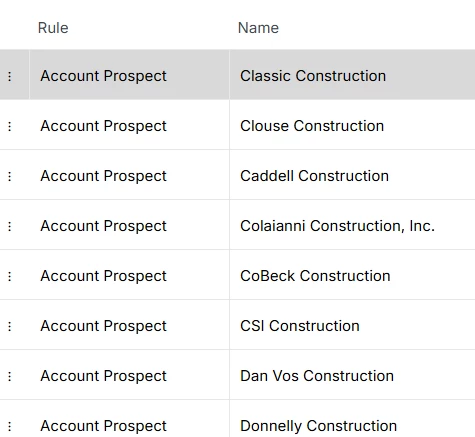
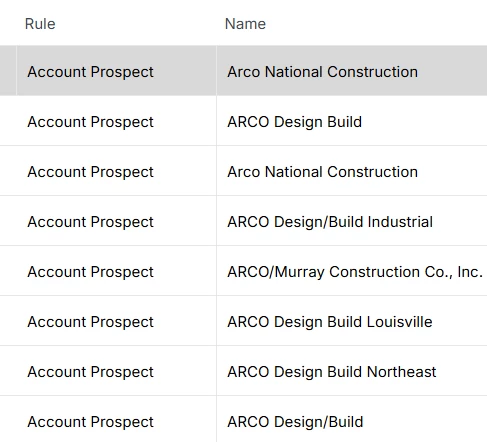
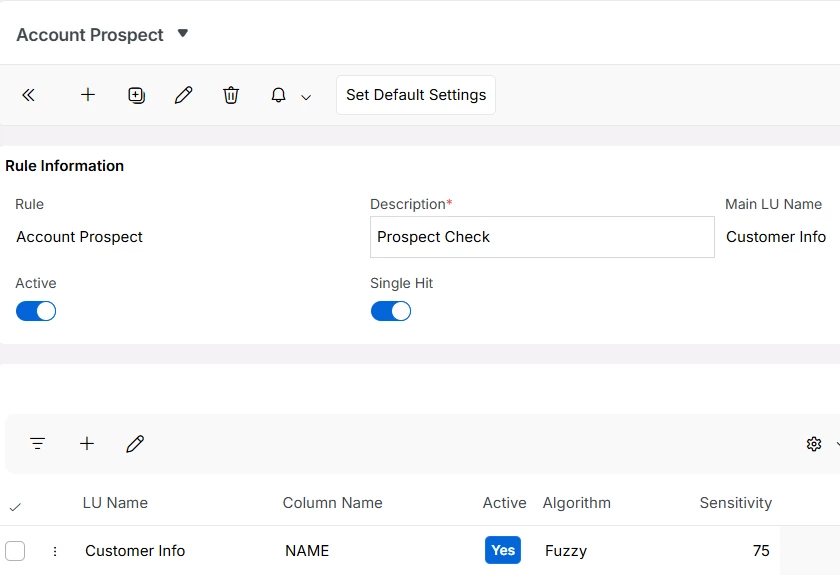
When creating a Duplicate Check Rule for Customer Info (Name), and the algorithm as fuzzy with a sensitivity of (75), I can get duplicates for the word “Arco” but if I have duplicates of “Carolina” it doesn’t pick it up. Has anyone run into a scenario like this?


1 reply

Jinal
Sidekick (Partner)
Forum|alt.badge.img+5
  • Sidekick (Partner)
  • September 7, 2026

This looks like a side effect of how fuzzy matching algorithms score similarity, rather than a bug in the Duplicate Check Rule itself.

Most fuzzy algorithms calculate similarity as a percentage of edit distance relative to the total string length. For a short word like "Arco" (4 characters), even a one- or two-character difference represents a large proportion of the string, so it's easy to stay above a 75% similarity threshold. For a longer string like "Carolina" (8 characters), or multi-word values like "North Carolina" vs "N. Carolina," the same absolute difference (a swapped word, an abbreviation, a missing prefix) makes up a much smaller percentage of the total length in some comparisons and a much larger one in others — so the score can swing below your 75% cutoff even though a human would clearly see it as a duplicate.

A few things worth trying:

  1. Test a lower sensitivity level (60–65%) specifically for longer or multi-word Name values, since the same percentage cutoff behaves differently depending on string length.
  2. Normalize the data before the check runs — strip or standardize common prefixes/abbreviations (e.g., "N." vs "North") so the fuzzy comparison works on cleaner, more comparable strings.
  3. Add a secondary matching field alongside Name (e.g., Tax ID, phone, or address) so the rule isn't relying solely on name similarity for longer entity names.
  4. If this is affecting production data quality, it may be worth logging a support case with IFS — the built-in fuzzy algorithm's threshold behavior for longer strings isn't something you can tune much further from the rule configuration alone.